Speakers, including overlap
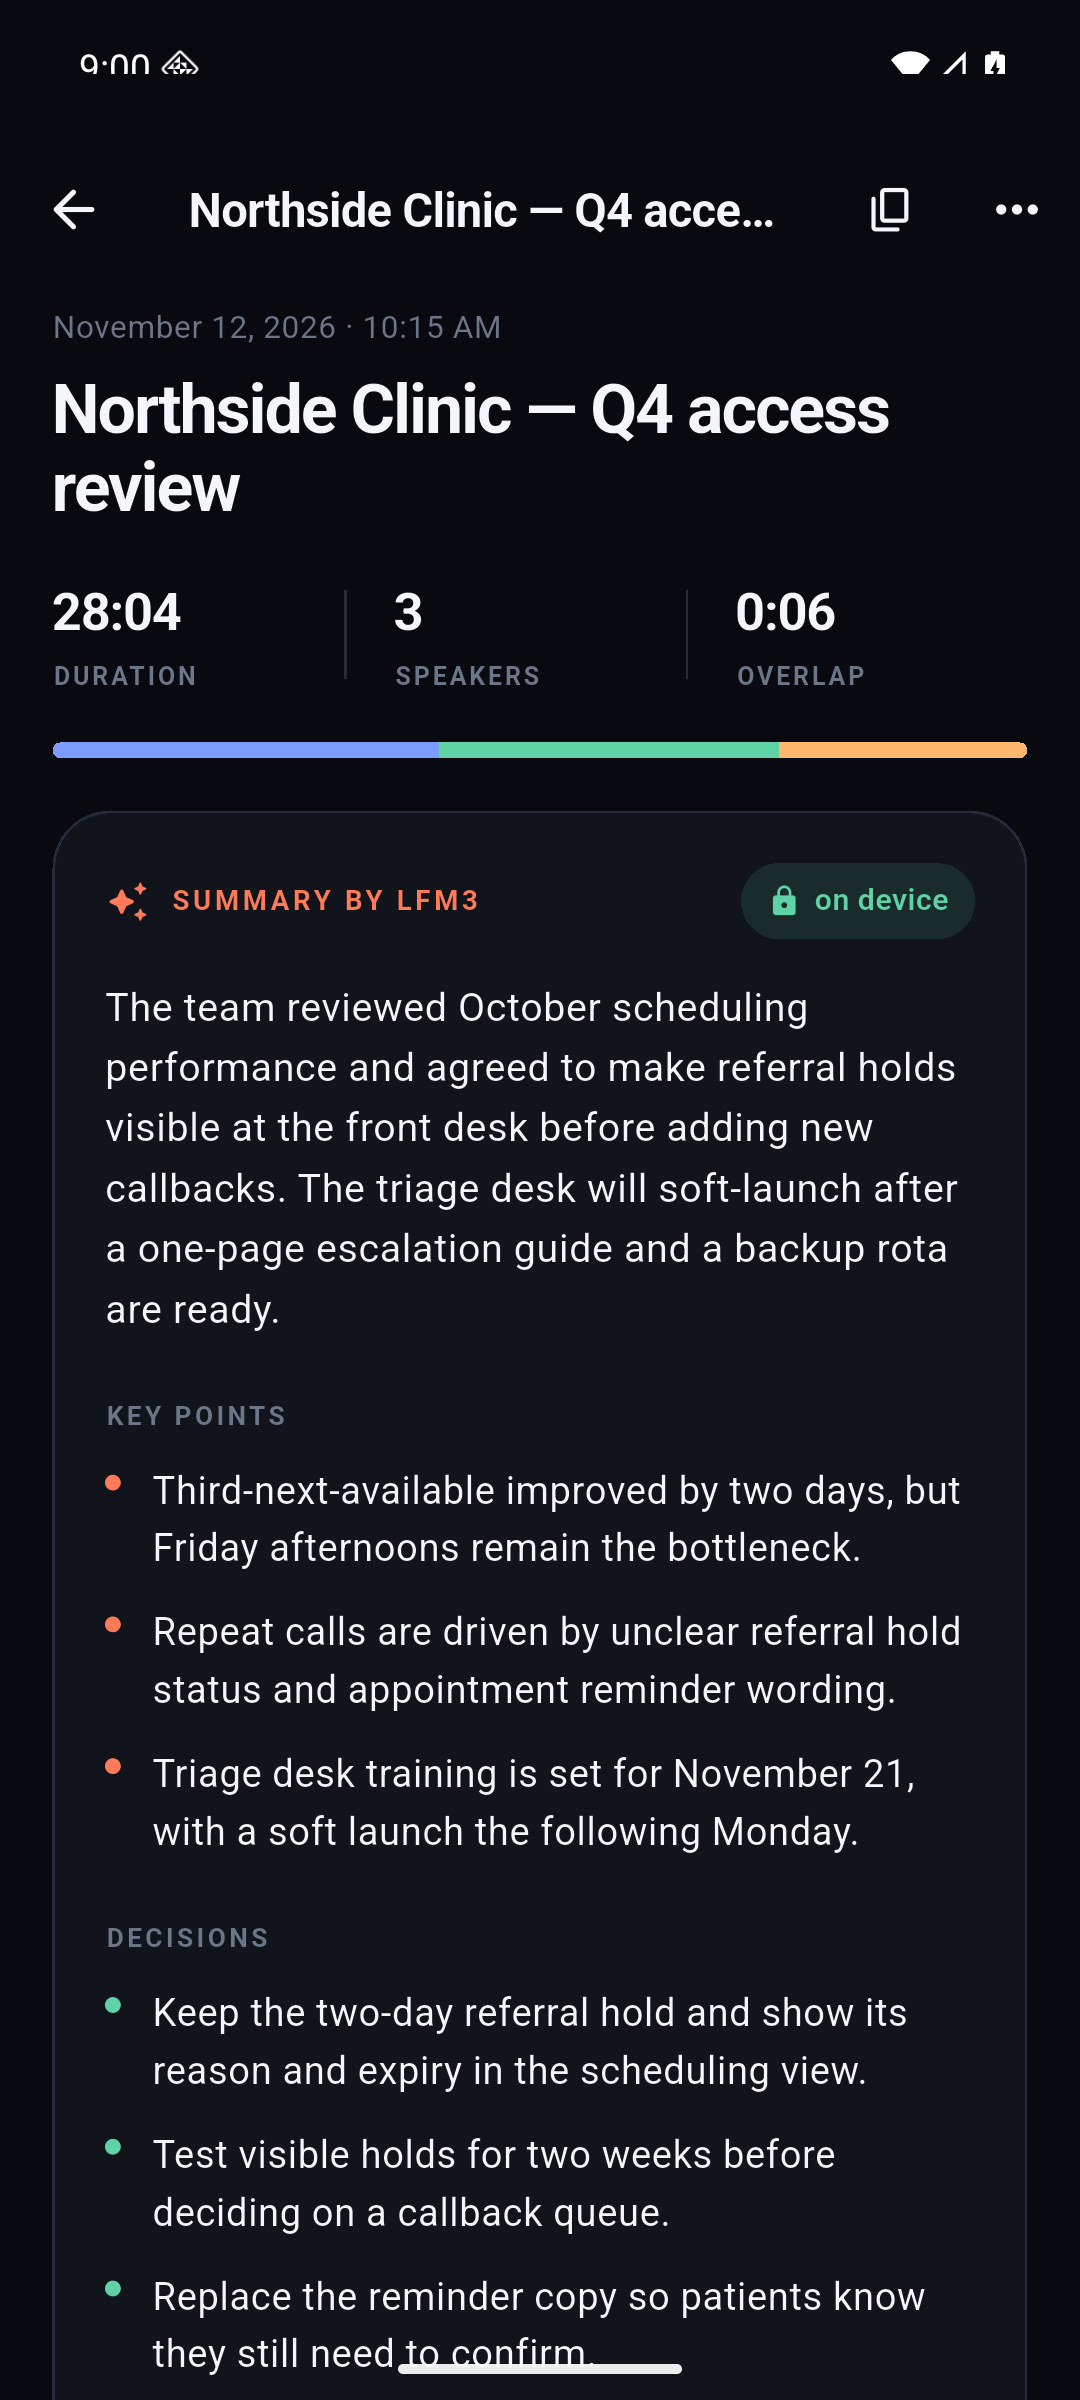
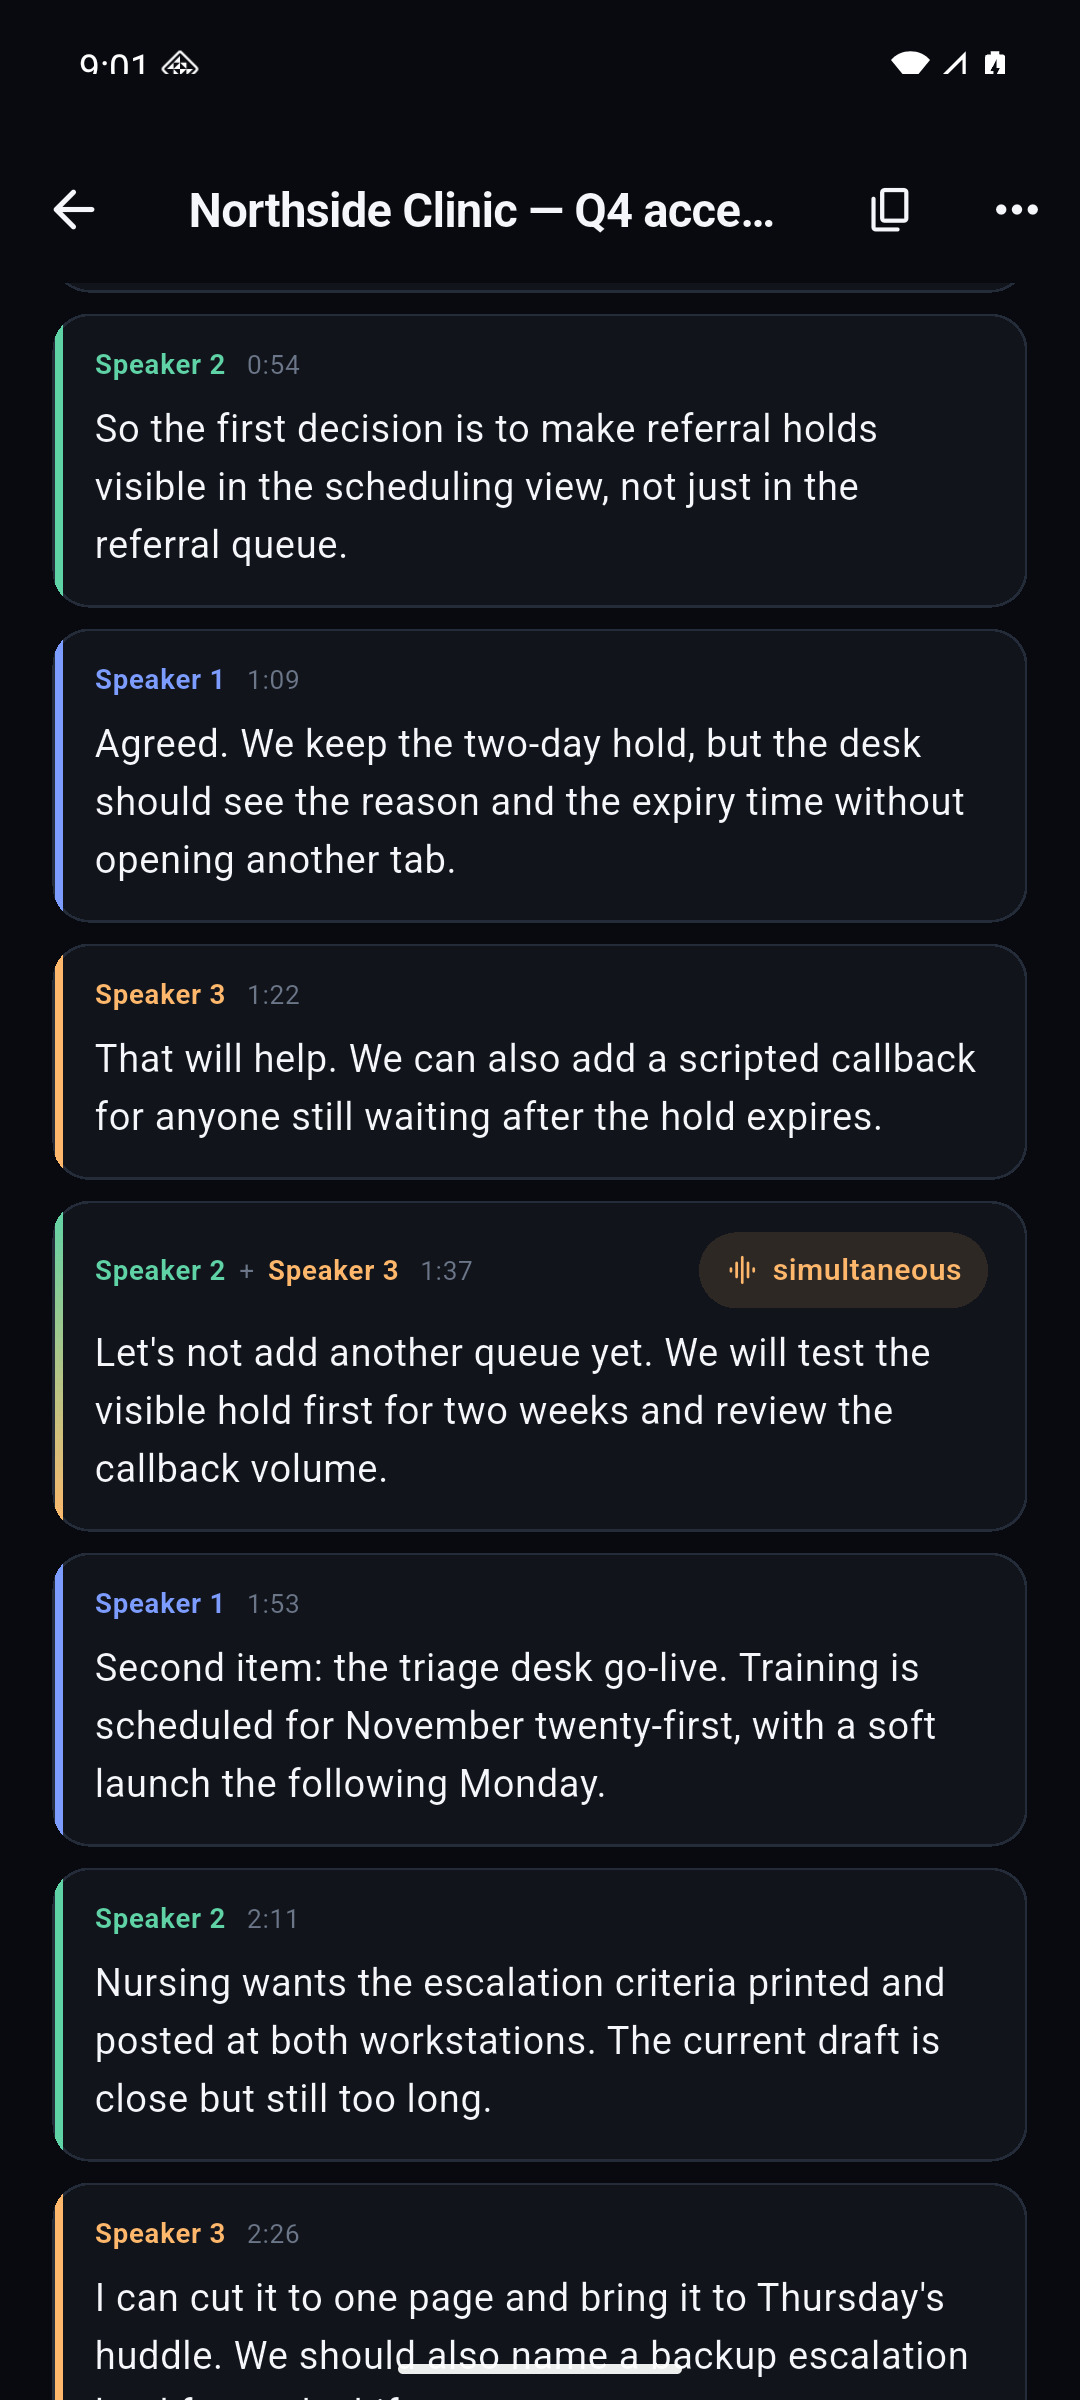
Every turn is attributed to a voice. When two people speak at once, the line carries both labels and a simultaneous-speech badge.
HOW IT WORKS
Three steps, all on the phone you already carry.
Start a recording in the room, or bring in an existing audio or video file. RecSum keeps the source on your phone.
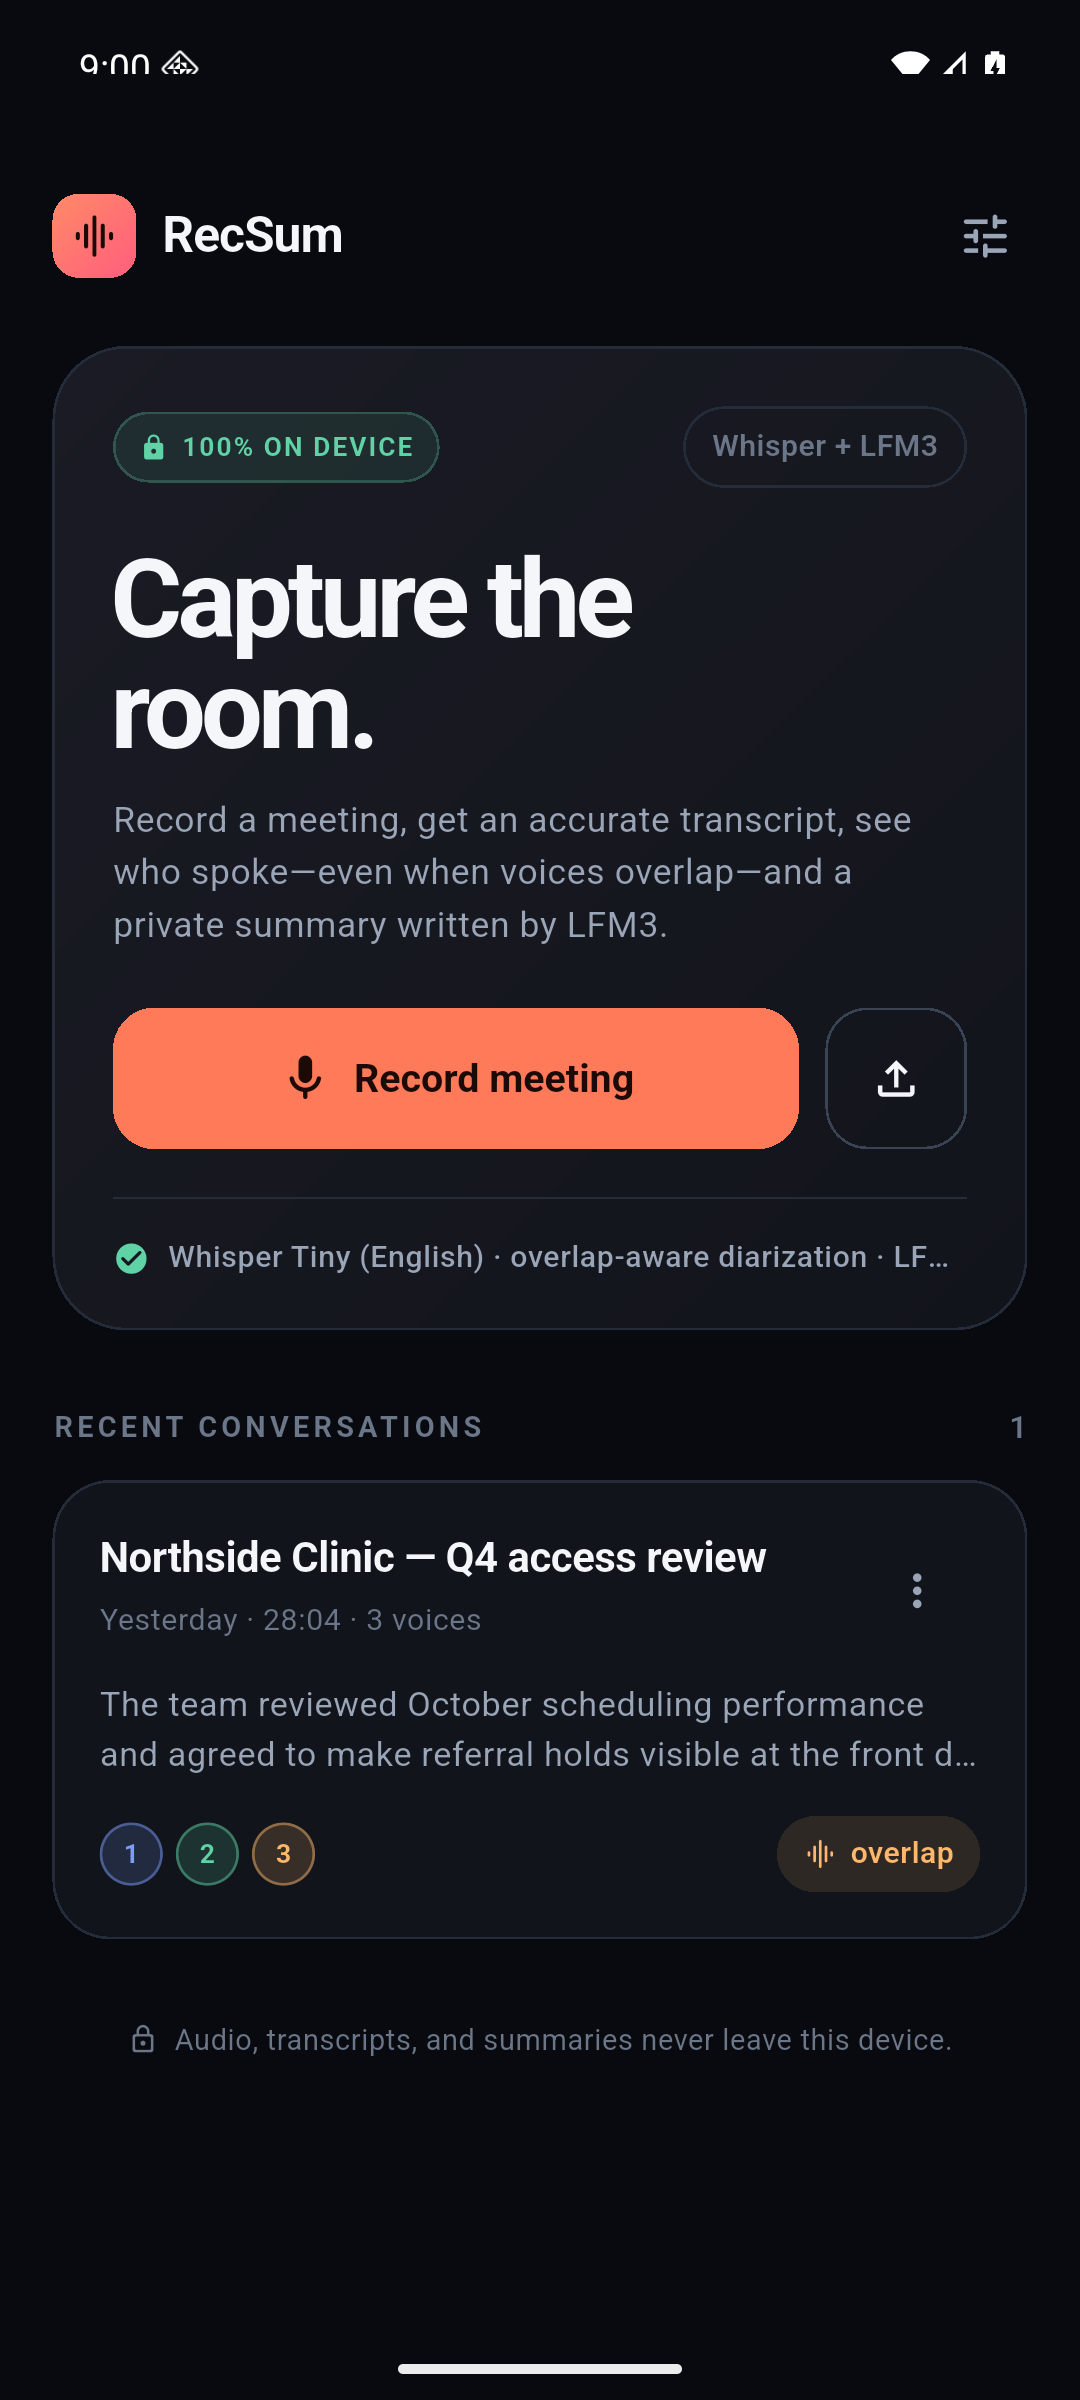
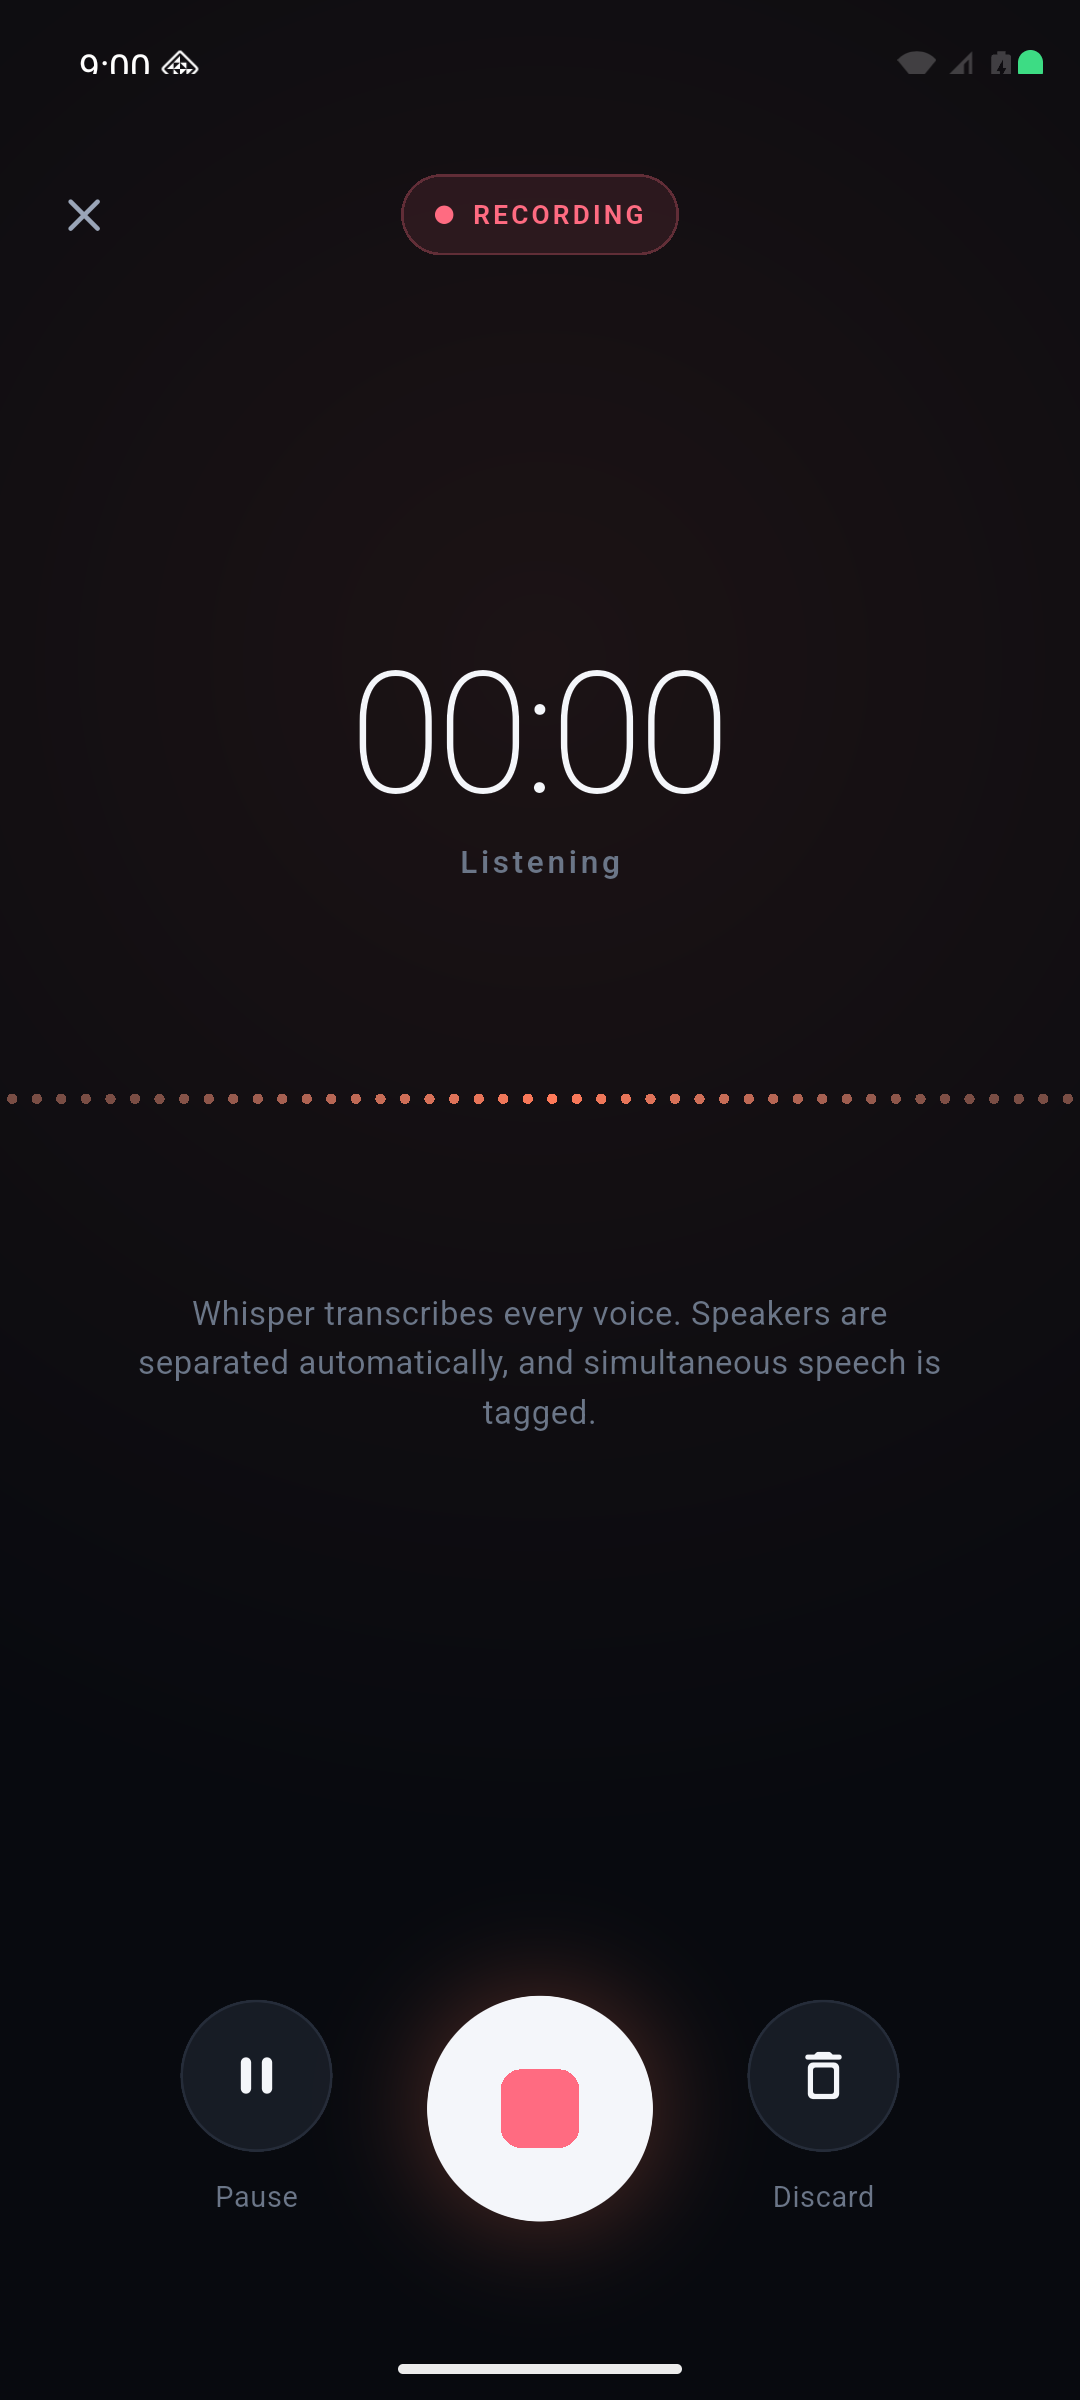
Whisper transcribes up to 99 languages. Speaker diarization labels each voice and flags moments when people talk over each other.
LFM3 1.7B writes the title, overview, key points, decisions, and action items on the device. No inference request leaves the phone.
INSIDE THE APP
WHAT YOU GET
Every turn is attributed to a voice. When two people speak at once, the line carries both labels and a simultaneous-speech badge.
Whisper handles multilingual meetings, with an English-only option when you want the smallest, fastest model.
The local summary separates what was decided from what happens next, so the recap is useful before you leave the room.
WAV, MP3, M4A, AAC, FLAC, OGG, Opus, MP4, MOV, and WebM. RecSum extracts and processes the audio locally.
Meetings, transcripts, and summaries live in the app's private storage on your phone. There is no cloud library to browse.
Download the speech and language models when you need them. Remove them from the app whenever you want the space back.
BUILT FOR CONFIDENTIAL WORK
Local by architecture, so confidentiality is a property of where the data lives—not a promise about what a server does with it.
CLINICIANS
Capture a patient conversation with consent, review the speaker-labeled transcript, and leave with decisions and follow-ups. No patient audio is sent to a summarization API.
LEGAL TEAMS
Record with consent and review who accepted which next step. The transcript and summary stay in your private library, with no third-party inference endpoint in the loop.
PRIVACY-FOCUSED
There is nothing to sign into and no audio leaves the phone. Download the models once, work offline, and delete a recording or the models whenever you choose.
PRIVACY BY ARCHITECTURE
Audio, transcripts, speaker labels, and summaries stay in the app's private folder on your phone. RecSum has no account system and no audio-upload path.
Read the privacy notesPrivate app storage · no server copy
QUESTIONS, ANSWERED
No. RecSum has no sign-in and no cloud account. Open the app, download the on-device models when prompted, and record or import a meeting.
No. Audio, transcripts, speaker labels, and summaries stay in the app's private storage on your phone. The only network step is downloading the models on first use; there is no audio upload.
Whisper transcription supports 99 languages. You can choose a language or let Whisper detect it, and the app offers a smaller English-only model when that fits your device.
iOS 16.4 or later, or Android 8.0 or later on arm64. In practice, plan for 4–6 GB of RAM. Larger models are slower; a 1.7B summary model and diarization models need room on disk.
Speech and language models download on first use, then stay on your device. After that, recording, transcription, speaker separation, and summarization work offline. You can delete the models from the app at any time.
Record only with the consent required in your jurisdiction and workplace. RecSum is built for transparent, local capture—not covert recording. You are responsible for following applicable law and policy.
RecSum makes no HIPAA, GDPR, medical-grade, or legal-compliance certification claim. It is designed for confidential work and is local by architecture. Your organization must decide whether it fits its own obligations and professional judgment.